Query the lake you already pay for.
Ward stands up a warehouse against your sources and keeps it current. You do not move your data lake to get one, and you do not pay to store it twice. Ward reads Iceberg, Delta and Parquet in place, and writes only where you tell it to.
A running warehouse over the storage you already own, with no migration window and no second copy.
Reads S3, Iceberg, Delta and Parquet in place. No lift and shift.
Incremental sync with change data capture where the source supports it.
Ward AI profiles what lands and drafts the cleaning and conforming rules. You review the diff in the console before any of it binds.
Your storage, your region, your retention policy.
Bring your own compute, or run on ours.
The migration question, answered on its own page: a data warehouse without the migration.
Three things have to be true. Two of them are yours.
Ward does not publish an hour-by-hour countdown, because the honest answer depends on how reachable your systems are and every vendor clock quietly assumes the best case. Here is the same information without the stopwatch: what makes a warehouse land the same day, and what pushes it to weeks.
The sources are reachable
Ward has to be able to open a connection to each system from where it runs. Cloud warehouses, hosted ERP and anything with a public endpoint are same-day.
What makes it weeks: An on-premises POS behind a firewall with no route out is a networking ticket, and that ticket is measured in days or weeks depending on who owns the firewall.
Read-only credentials exist
One scoped service account per source, SELECT on the schemas you name. Nothing needs admin and nothing needs write.
What makes it weeks: If every credential goes through a change advisory board that meets on Thursdays, the warehouse stands up on Thursday. This is the most common reason a fast setup is not fast.
Someone can approve the definitions
Ward AI drafts the cleaning rules, the pipelines and the metric definitions from the reports your team already publishes. A human has to approve the diff before any of it binds.
What makes it weeks: If nobody in the room can settle what a comparable store or a net sale means, that is not a Ward problem and no tool shortens it. It is the reason warehouse projects outlive their quarter.
Nothing on that list is a build. There is no ETL to schedule, no modelling layer to write and no platform to install, which is why the remaining work is credentials and approvals. If you want the version of this argument aimed at the migration question specifically, it is on a data warehouse without the migration.
A retail warehouse is useful long before it is complete.
Connect in the order things become answerable, not the order they appear on the architecture diagram. The first three cover most of what a merchandising, supply chain or store operations team asks in a week.
| Connect | What becomes answerable |
|---|---|
| POS | Transaction line items, by store, by day. Enough on its own for sales, basket and margin questions. |
| Inventory and merchandising | On-hand, receipts and movement joined to the transaction, which is where shrink, stockouts and fill rate become answerable. |
| ERP or finance | Cost, vendor terms and the general ledger, so a margin number reconciles to the one finance publishes. |
| E-commerce | The online half of demand, joined to the same SKU and the same store catchment. |
| Labor and scheduling | Hours against traffic, which turns a sales anomaly into a staffing answer instead of a question. |
| Supplier and EDI feeds | Inbound commitments and actual delivery, which is where fill-rate disputes get settled with a number. |
Whether yours is on the managed connector list is worth checking before anything else: the connector catalog. What Ward computes once a source lands, by industry, is on the industry pages.
Standing one up, and how long it really takes.
Including the version of the question with the honest answer attached.
The fastest path is to query what you already have rather than move it. A managed warehouse like Snowflake, BigQuery or Redshift plus a managed pipeline like Fivetran and a modelling layer like dbt will have rows landing within a day, and that is the standard answer, but the schedule after that is the modelling, not the loading. Ward compresses the modelling step instead of the loading step: it reads your sources in place on read-only credentials and reconstructs the metric definitions from the reports your team already publishes, so the first queries run in hours and the definitions arrive as a diff to approve rather than a quarter of work.
Getting data into a warehouse takes a day or two with managed connectors. Getting a warehouse people will quote in a board meeting takes most teams one to two quarters, and the difference is the semantic work: agreeing what each metric means, reproducing the numbers the old reports produced, and reconciling the two until finance stops flagging them. Any timeline that only counts ingestion is measuring the easy half.
Yes, when three things are true: the sources are reachable from where the warehouse runs, read-only credentials exist or can be issued the same day, and someone with authority to say what a metric means is available to approve the drafts. Ward is built around those three. The first is usually a networking question, the second is usually a ticket, and the third is the one that actually decides whether it is hours or weeks.
Connect the systems that carry the transaction first and add the rest afterwards. In practice that is POS, inventory and merchandising, then ERP or finance, then e-commerce, then labor and supplier feeds. Those first three answer most of what a retail team asks, which means the warehouse is useful before it is complete. Ward connects each on a read-only service account, drafts the cleaning and conforming rules for what lands, and rebuilds the definitions behind the reports the team already circulates.
You need someone who can issue credentials and someone who can settle what a metric means. Those are the two blocking roles, and on most teams they are a platform engineer and a finance or operations lead rather than a dedicated data engineer. The work that normally requires a data engineering team is the pipeline and modelling layer, which is what Ward AI drafts for review. The approval still belongs to a human, because a definition nobody signed off is a definition nobody will defend.
Deploying Ward is free and there is no license. The only recurring fee is 5% of the model compute that routes through it, metered on your own provider keys and billed monthly in arrears. Setup is one-time and covers training and guidance rather than the software: self-guided is $0, guided is $7,500, and managed is $20,000. Storage and any compute you bring stay on your own cloud bill, where they already are.
What this looks like when you actually use it.
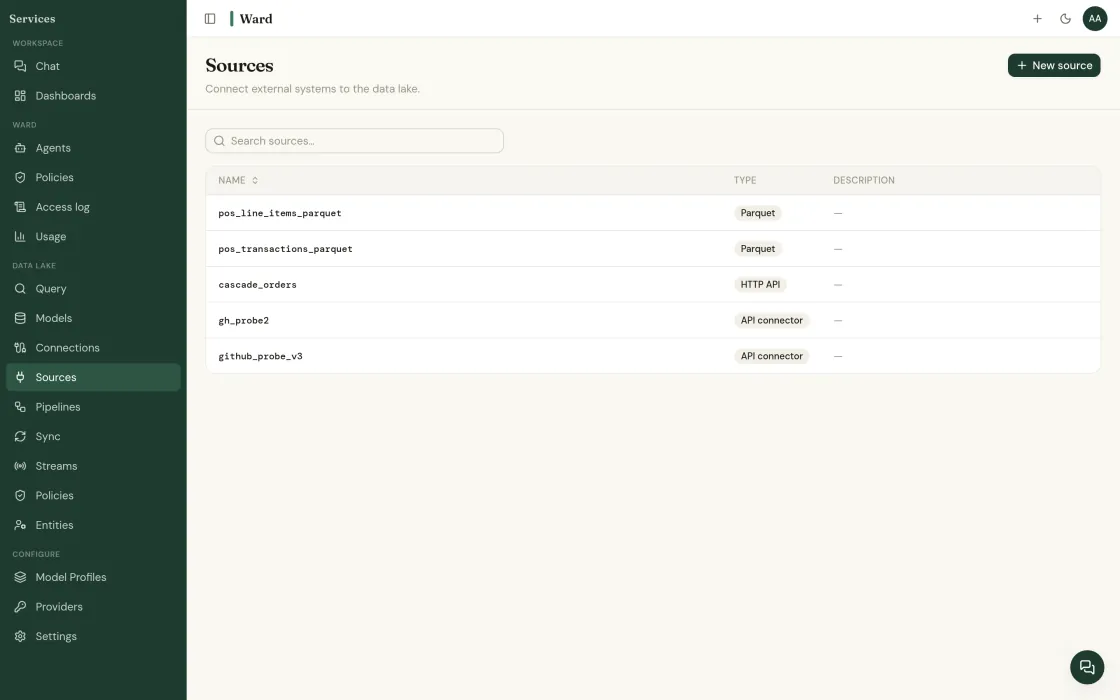
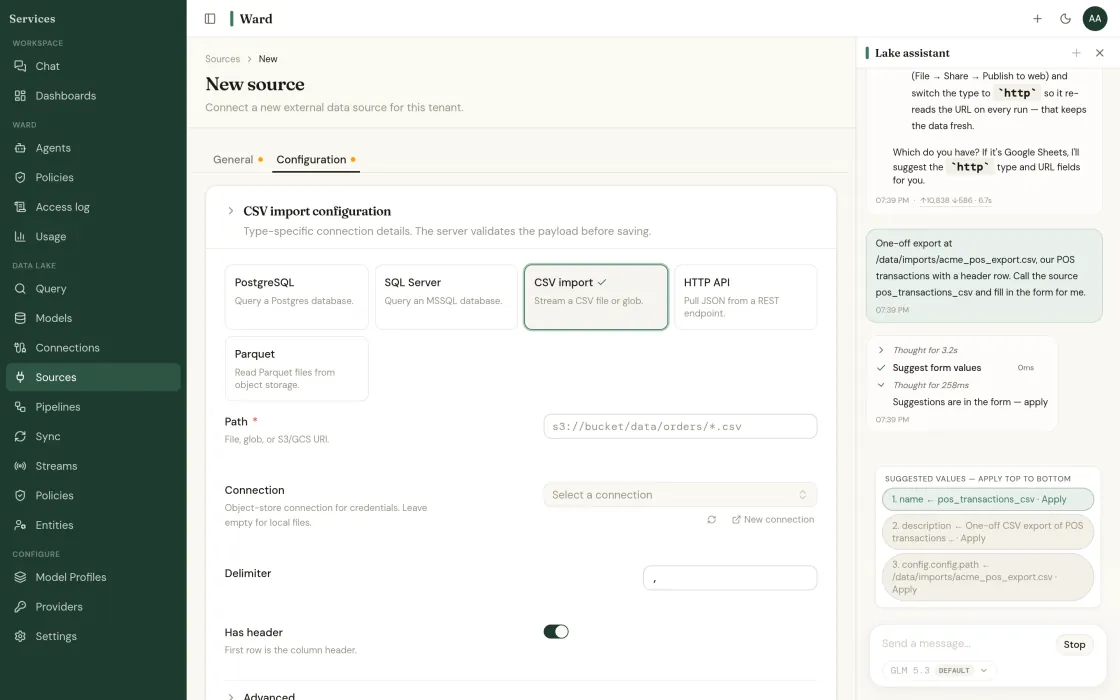
Add a source
Sources, then + New source. Pick your warehouse, lake, ERP or POS and give Ward a read-only credential scoped to the schemas you name. Ward reads the schema and shows you what it found before anything else happens.
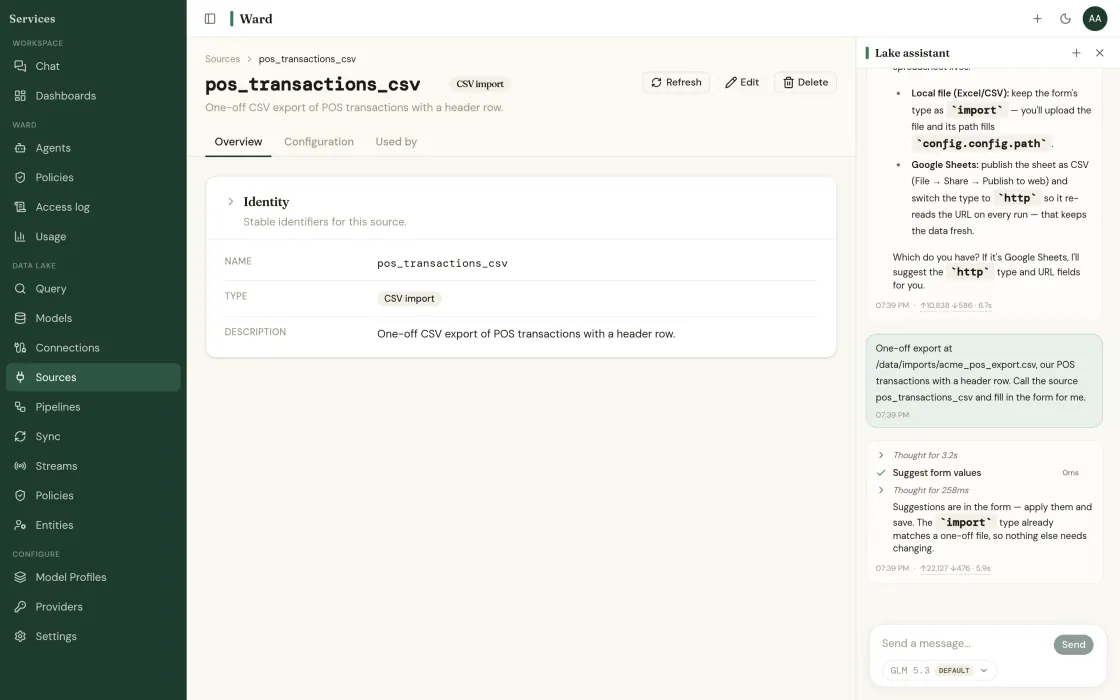
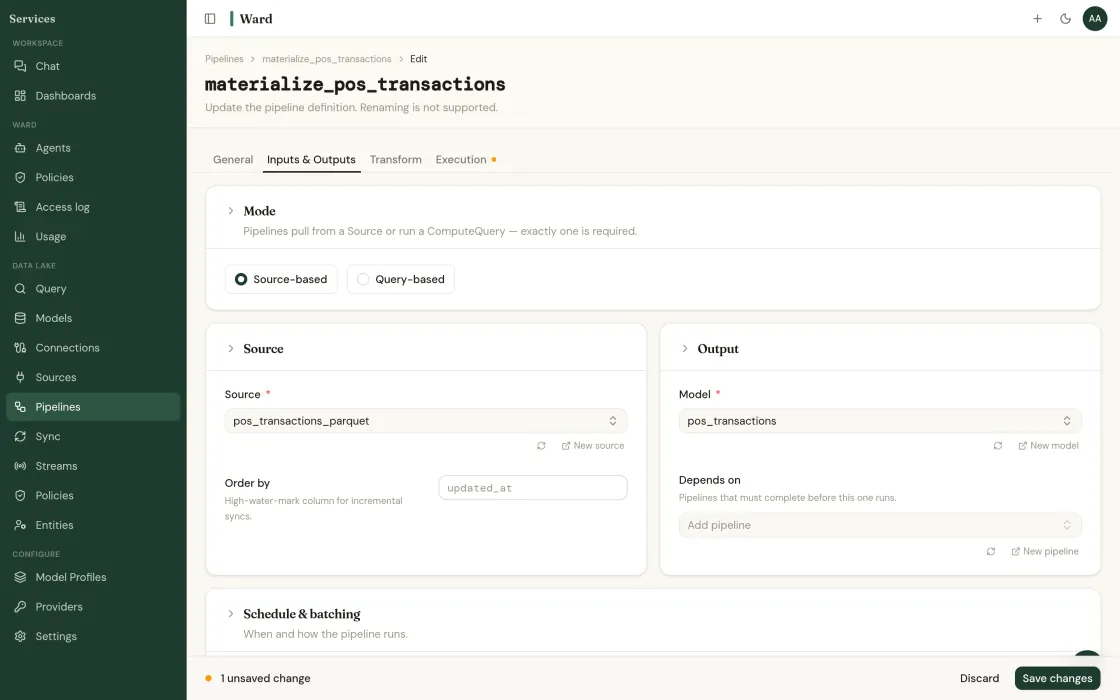
Review what Ward AI drafted
Ward profiles what landed and drafts the cleaning and conforming rules. They arrive as a proposal, not as a running pipeline. You read the diff and approve it, the same way you would review a colleague's work.
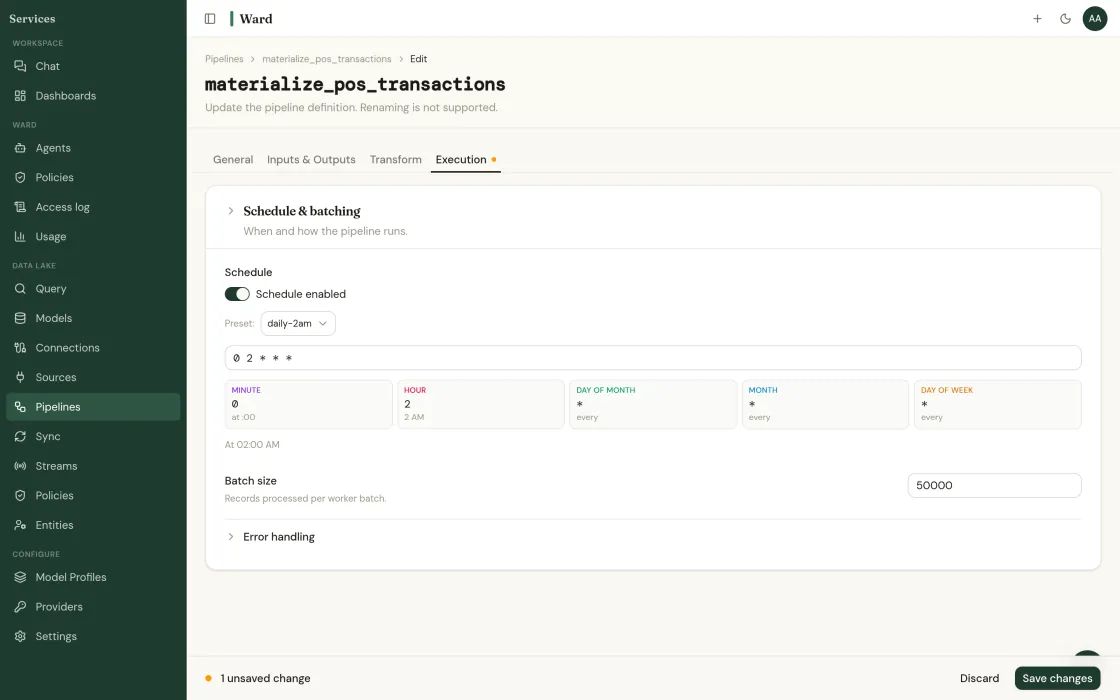
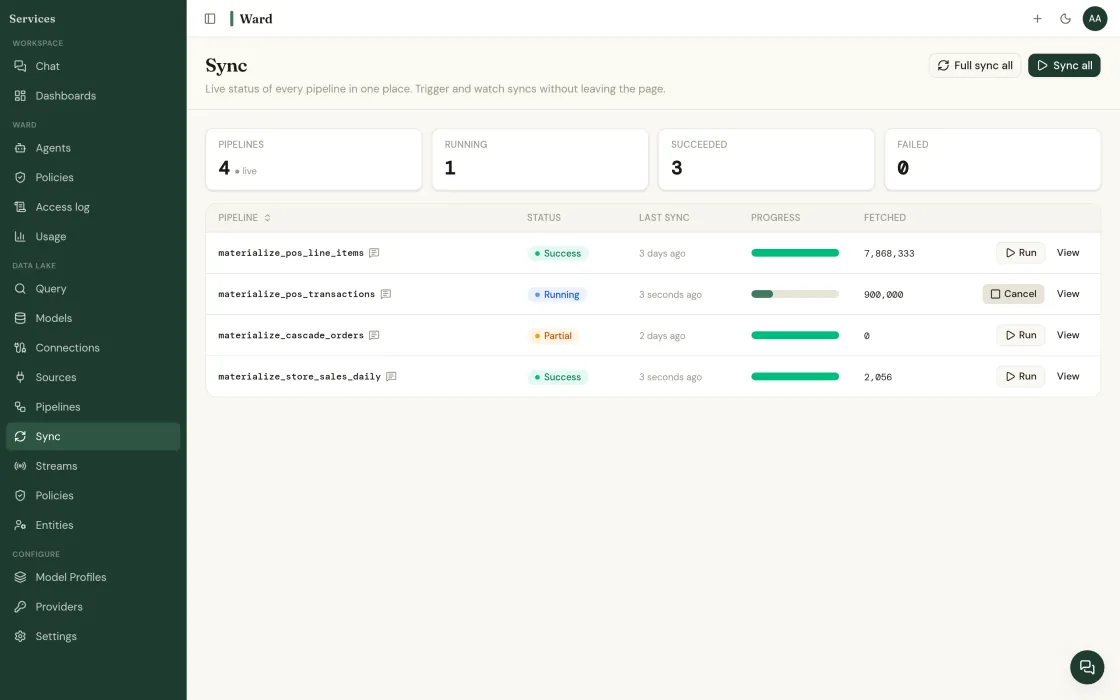
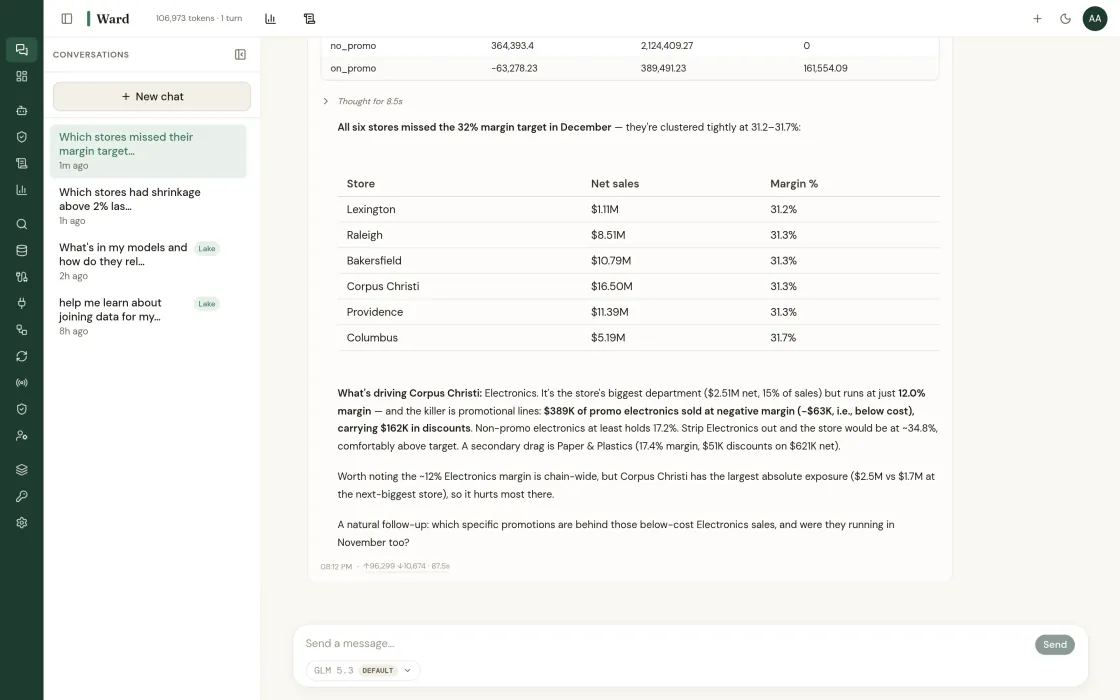
Five more primitives. Adopt them in any order.
Connectors
540 sources. Read-only by default.
Managed ingestion from warehouses, lakes, SaaS APIs, databases and flat files.
Read more →Semantic layer
One definition of revenue. Enforced.
Metrics, dimensions and grain defined once and enforced everywhere, including in what agents are allowed to compute.
Read more →Agent runtime
The warden of your data and your agents.
A governed runtime for building agentic logic against your own data, with every action scoped and logged.
Read more →Query and chat
Ask in English. Read the SQL.
Natural language over the semantic layer, with the generated SQL always visible.
Read more →Governance
The answers your security review needs.
Row-level policy, scoped credentials, and an audit log that covers humans and agents equally.
Read more →Start with one source.
Deploying is free. The whole console, every connector, and nothing to license.
Read-only to start · your LLM keys · SOC 2 Type II underway · or book a call directly
Find out what your data has been hiding.
Tell us about your operation. We’ll show you the problems Ward catches, and the ones your current tools miss.